01 · Reason
Reinforcement Learning & Post-Training
I teach language models which earlier steps to focus on, so they reason more accurately with shorter answers.
Machine Learning Engineer & Researcher
I am a Machine Learning Engineer at ACI PLC, where I build machine learning systems that run in the real world. Before that, I was an AI Engineer at Ontik Technology, developing agentic AI applications.
My latest first-author work, OPASD, teaches reasoning language models where to look. This work is supervised by Dr. Md Mofijul Islam (Amazon GenAI, USA) and Dr. Tasnim Mohiuddin (Qatar Computing Research Institute, Qatar). I am also working with Dr. Ser-Nam Lim (University of Central Florida, USA) on world models.
I earned my B.Sc. in Robotics and Mechatronics Engineering from the University of Dhaka. After graduating, I worked on amodal counting with Dr. Md Mehedi Hasan (University of Dhaka, Bangladesh) at the AVIS Research Lab. As an undergraduate, I worked on sign language translation with Dr. Shafin Rahman (North South University, Bangladesh) and Dr. Sejuti Rahman (New Uzbekistan University, Uzbekistan).
Outside of research, I play basketball, train at the gym, and travel whenever I can. I am always glad to meet curious people, so please feel free to reach out.
I am actively seeking MS/PhD opportunities for Fall 2027.
Research interests
Most agents learn from outcomes, which tell them whether they succeeded but not why. My work gives an agent richer signals across the three abilities it needs. To reason, it learns where to look, not just which answer is right. To perceive, it fuses modalities so that one view fills in what another misses. To act, it learns why it failed, as a vision–language model turns its mistakes into rewards.
01 · Reason
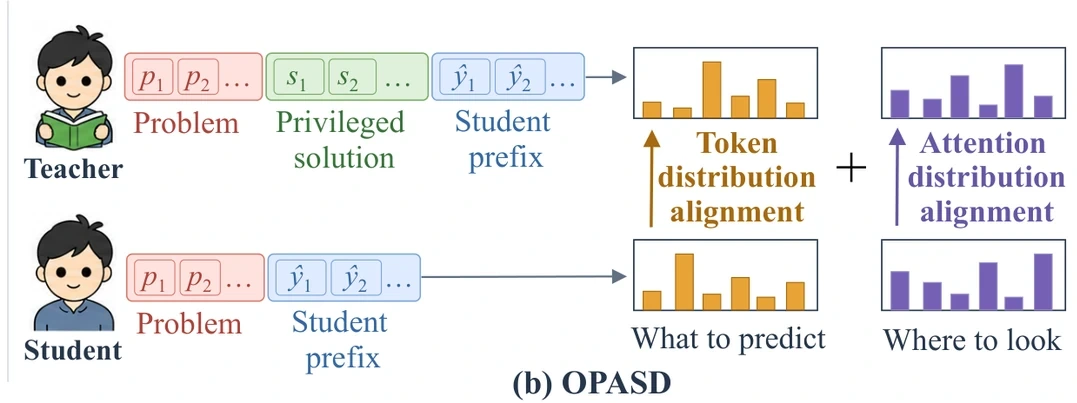
I teach language models which earlier steps to focus on, so they reason more accurately with shorter answers.
02 · Perceive
I fuse complementary modalities, like video with body pose or time series with text, so models capture what any single view would miss.
03 · Act
I use vision–language models to explain why a robot failed and turn that feedback into rewards.
New Our new preprint, Teach Yourself Where to Look, is now on arXiv.
Our paper LAGEA: Language Guided Embodied Agents for Robotic Manipulation has been accepted at ICML 2026.
Our work T3Time has been accepted at the AAAI 2026 Main Technical Track.
SignFormer-GCN has been accepted at the WiML Workshop at NeurIPS 2025.
Started as a Machine Learning Engineer at ACI PLC.
SignFormer-GCN is officially published in PLOS ONE.
Graduated from the Department of Robotics and Mechatronics Engineering, University of Dhaka.
Joined Ontik Technology as an AI Engineer.
Successfully defended my undergraduate thesis — a huge milestone in my academic journey.
Presented our poster Classical machine learning approach for human activity recognition using location data at UbiComp/ISWC 2021.
On-policy self-distillation tells a student what to predict, but not where to look. OPASD adds solution-conditioned attention distillation, projecting a privileged teacher's attention onto student-visible context. It beats token-only OPSD by 4.98–8.40 points across three Qwen3 sizes while cutting rollout tokens by 73.9%.
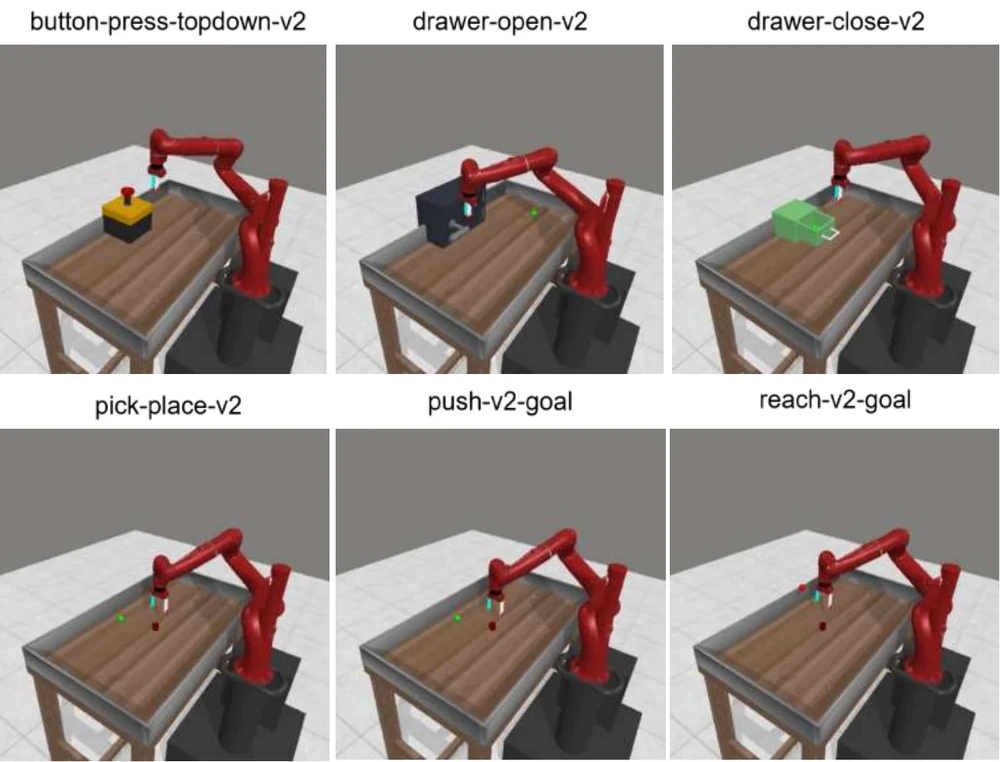
LAGEA turns structured vision-language-model reflections on a robot's own failures into temporally grounded, progress-based shaping rewards. It localizes the decisive moments of an episode, aligns feedback with visual states, and fades the guidance as the policy improves, outperforming FuRL on Meta-World MT10 and Fetch.
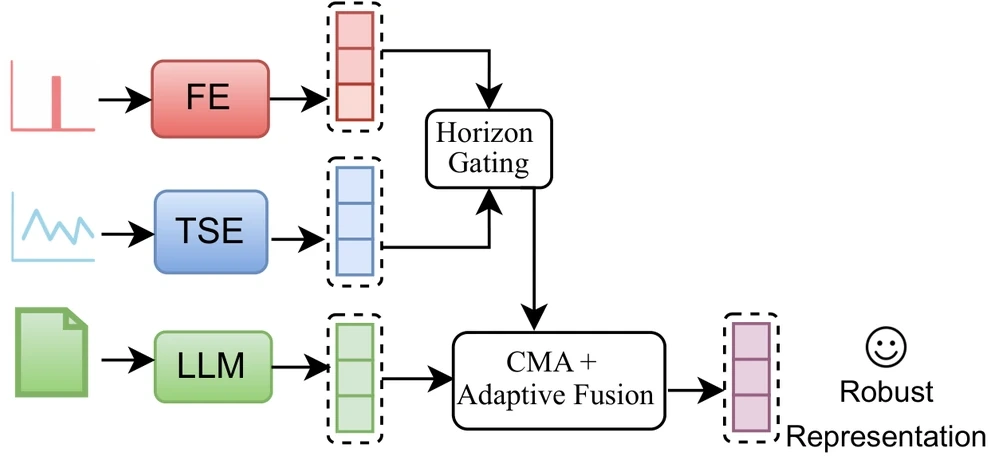
T3Time reads a time series three ways (temporal, spectral, and through an LLM prompt), gates temporal versus spectral features by forecast horizon, and fuses modalities with adaptively weighted cross-modal attention heads. It sets the best MSE on 7 of 8 long-term benchmarks and stays strong with only 5–10% of the training data.
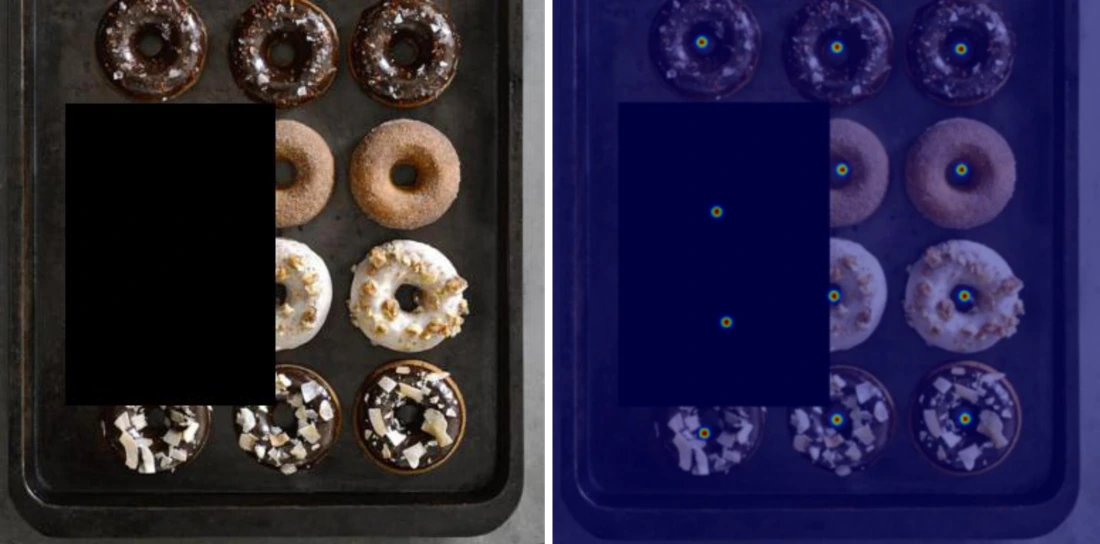
State-of-the-art counters only count what they can see. CountOCC reconstructs the features of hidden objects from visible context and text/exemplar priors, and enforces attention consistency between occluded and unoccluded views. It sets a new state of the art on our occlusion benchmarks FSC-147-OCC and CARPK-OCC, and on CAPTURe-Real.
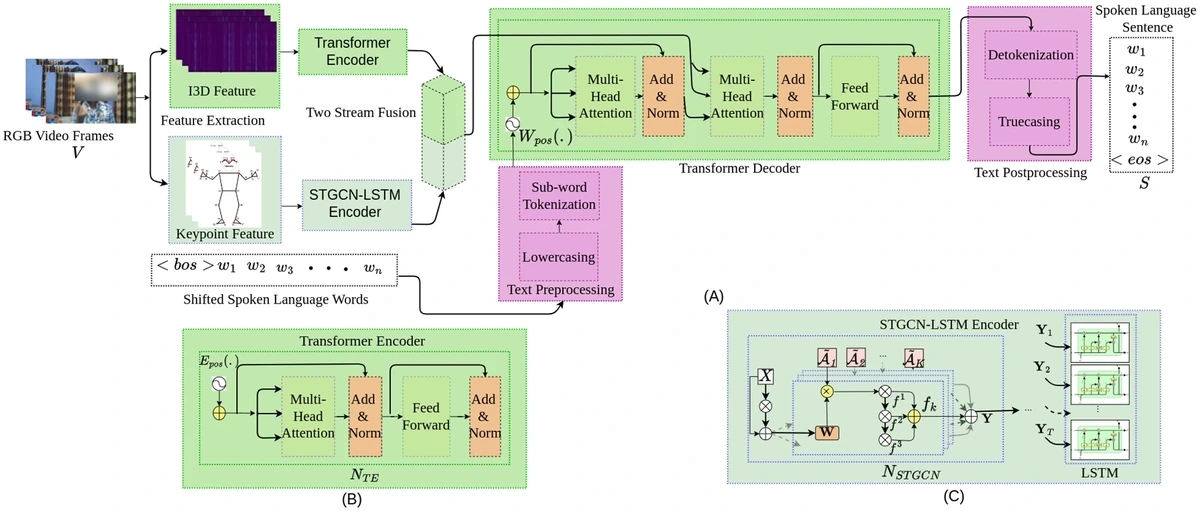
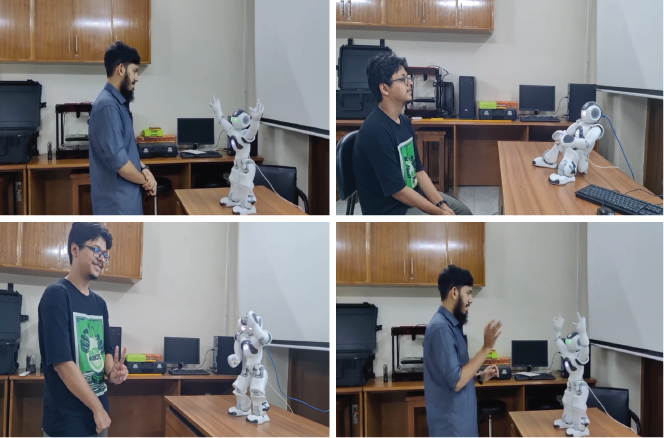
SignFormer-GCN jointly encodes RGB video with a transformer and skeletal keypoints with an STGCN-LSTM, capturing both broad context and fine-grained body motion. It delivers competitive gloss-free translation on German, American, and Bangla sign language benchmarks with only 9.43M parameters.
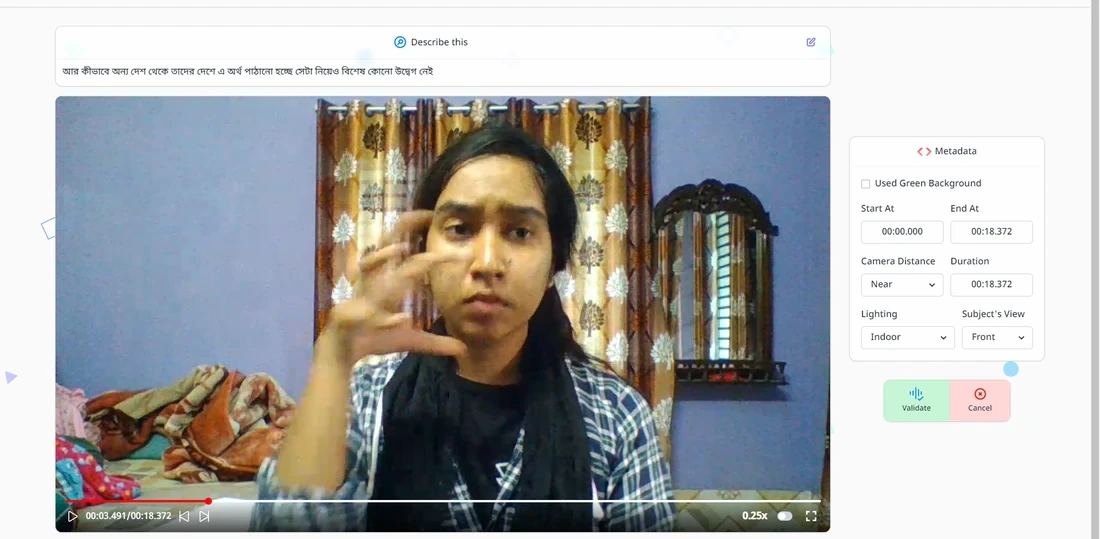
Bornil is an open-source platform for recording, annotating, and validating multilingual sign language data. It was used to build BornilDB v1.0, the largest Bangladeshi Sign Language dataset (73 hours, 21,000+ samples), with recognition benchmarks for this low-resource setting.
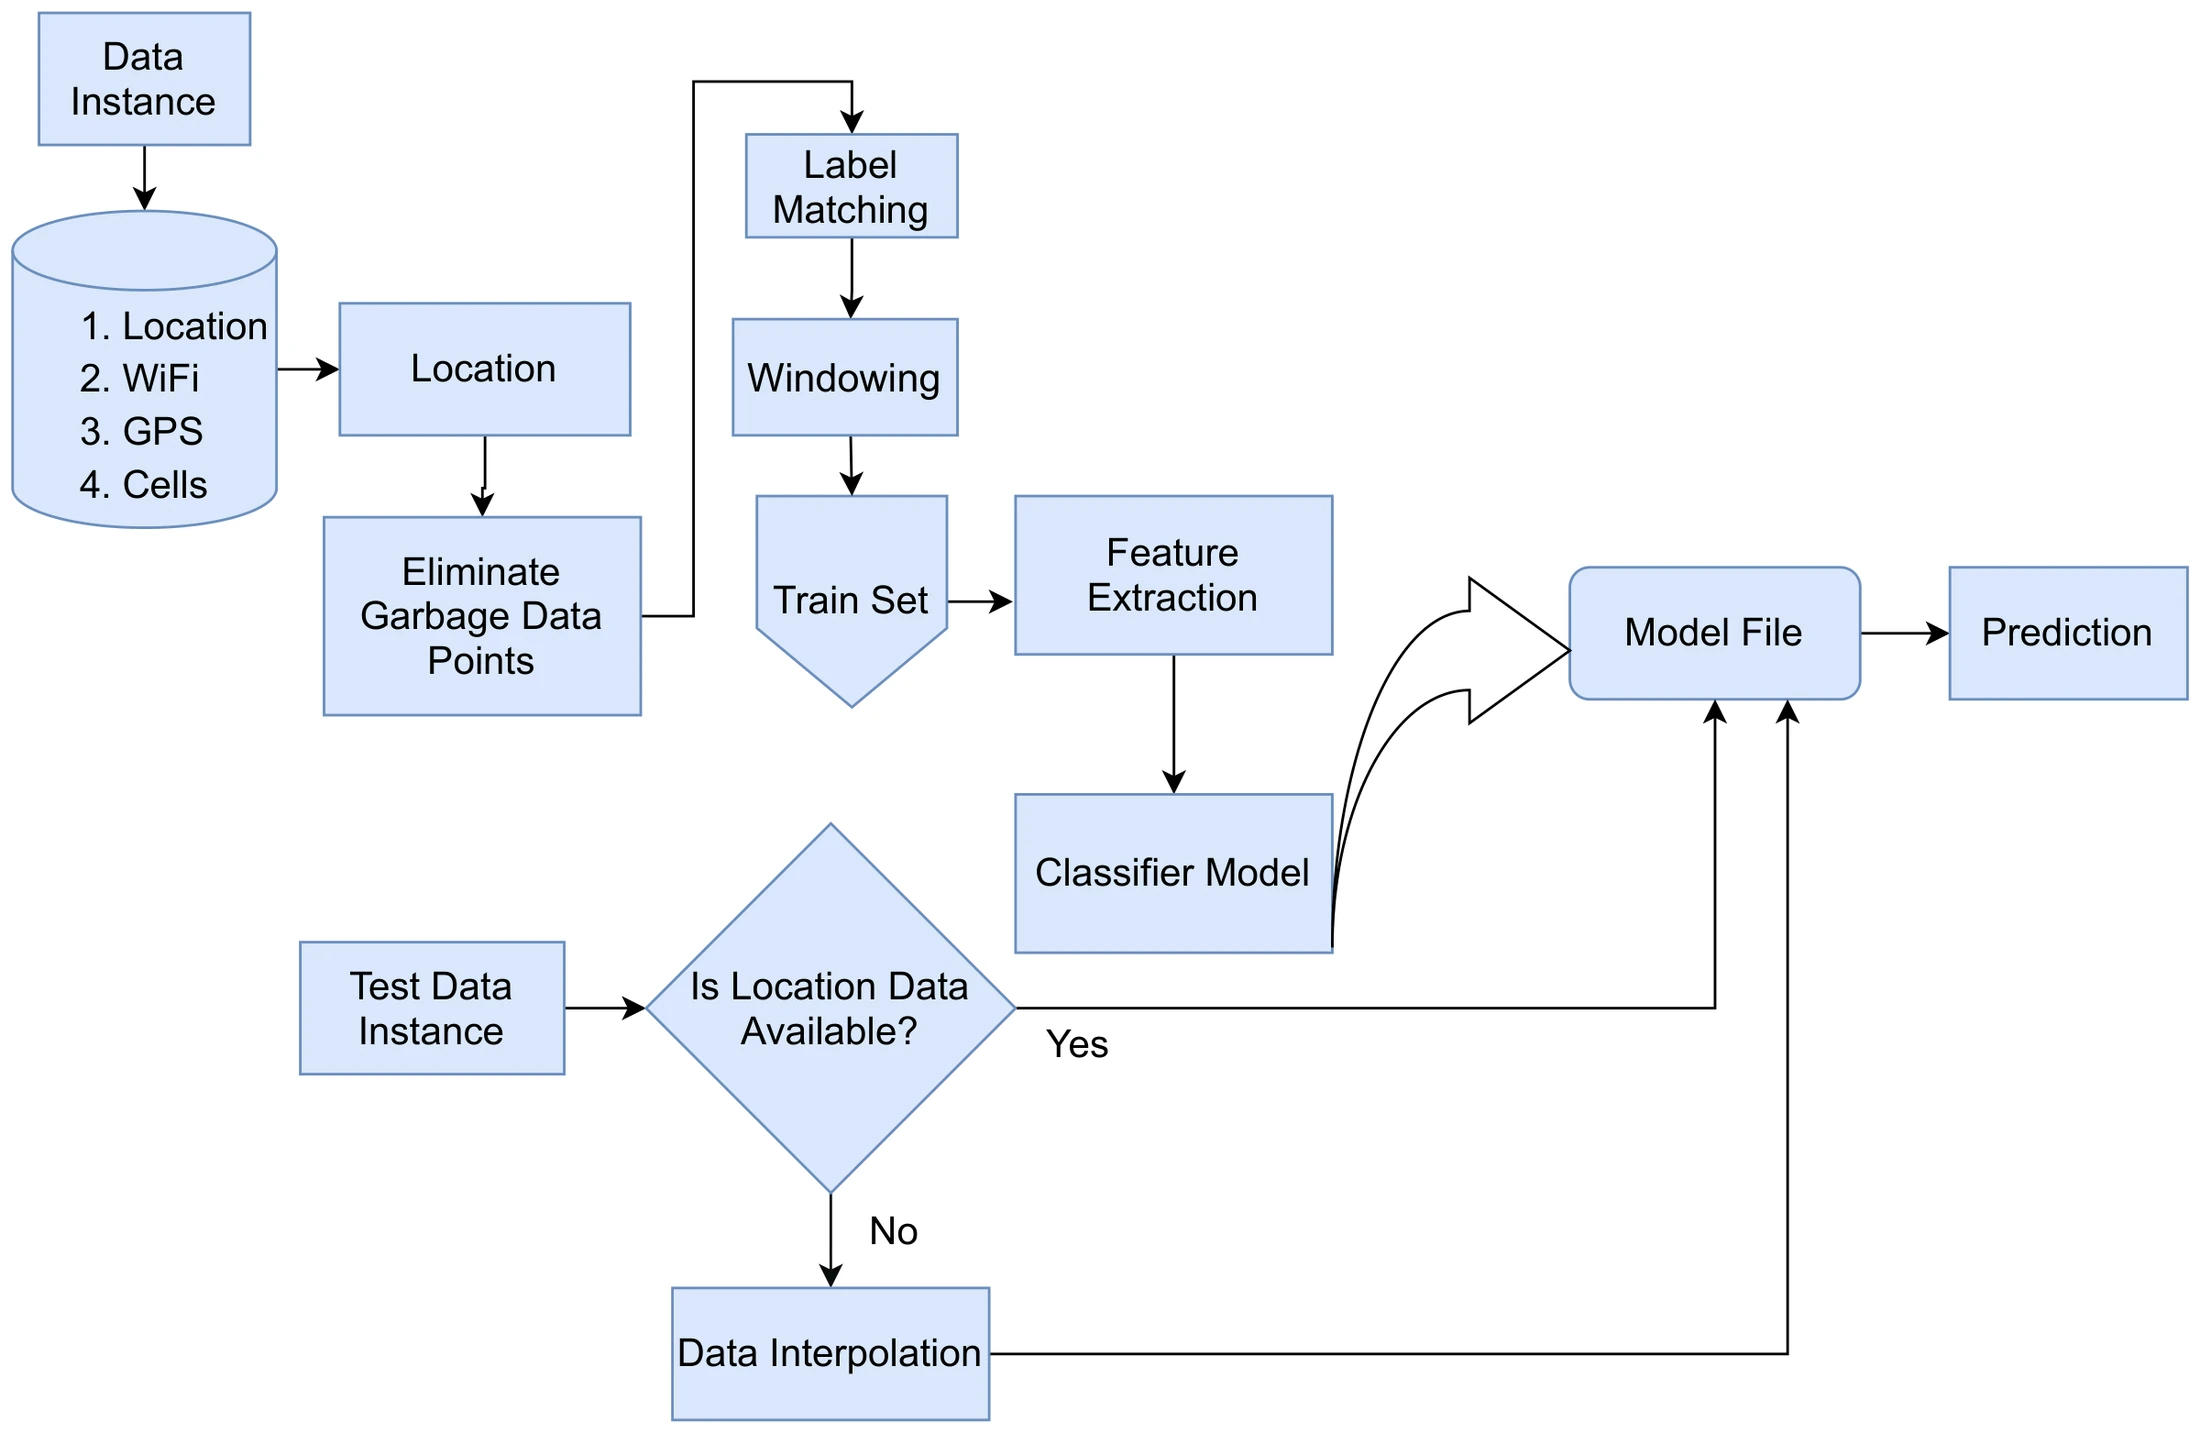
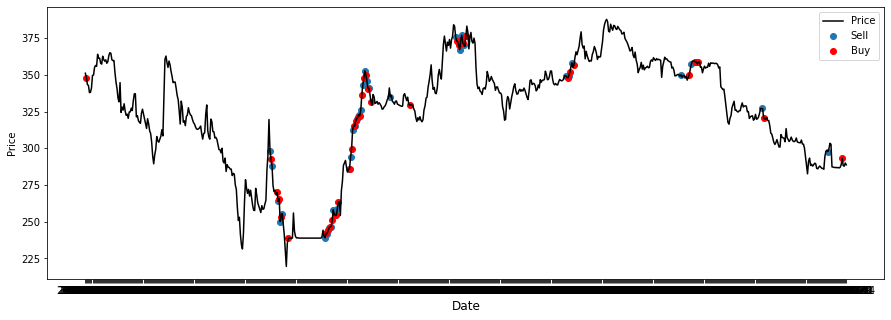
Our entry to the Sussex-Huawei Locomotion Challenge 2021 recognizes eight locomotion and transportation activities from smartphone location data using statistical features and a random forest, reaching 78.14% validation accuracy and a 78.28% weighted F1 score.
Dept. of Robotics and Mechatronics Engineering, University of Dhaka · with Dr. Md Mehedi Hasan and Md. Jubair Ahmed Sourov
Dept. of Robotics and Mechatronics Engineering, University of Dhaka · with Dr. Shafin Rahman and Dr. Sejuti Rahman
ACI PLC · Dhaka, Bangladesh
Ontik Technology · Dhaka, Bangladesh
National Camp, Bangladesh Artificial Intelligence Olympiad